Prompt Alignment 衡量生成视频在 benchmark 协议锚点帧上与目标指令 T=sample.prompt_target 的语义一致程度。它评估预测在采样时刻是否实现所请求的场景内容,而非整段 rollout 的时序连贯性或视觉真实性。
记 A={fi}i=1M 为评测协议从解码预测中选取的锚点帧集合。设 CLIP ViT-B/16 图像编码器为 ϕI、文本编码器为 ϕT,L2 归一化嵌入为 ei=ϕI(fi)、t=ϕT(T)。帧 i 的原生 CLIPScore 为
si=max(100⋅⟨ei,t⟩,0)(1)
WorldAtlas 将各锚点得分映射至 [0,1]:s~i=clamp(si/100,0,1),并报告均值
Sprompt=M1i=1∑Ms~i(2)
Sprompt 越高,表示协议锚点处的指令跟随越强。当存在显式指令监督且 conditioning 非自参照(conditioning_strategy ≠ self)时,该指标为 official。图像套件可以单帧图像为条件,但模型输出仍须为视频。
下方案例从完整的 2026-07-17 image_static 快照中人工筛选:20 个模型在相同的 3,372 个 case 上评测。每组左右视频都经过严格校验,sample ID、条件图像 SHA-256 和实际生成 prompt SHA-256 完全一致,且两条 generation record 都明确把该图作为 conditioning input;“好/差”仅描述 Prompt Alignment,不代表整体视频质量。每个分数均为四个 segment_random 协议锚点的平均值。
Audit manifest: docs/assets/metric_examples/curated_same_case_manifest.json.
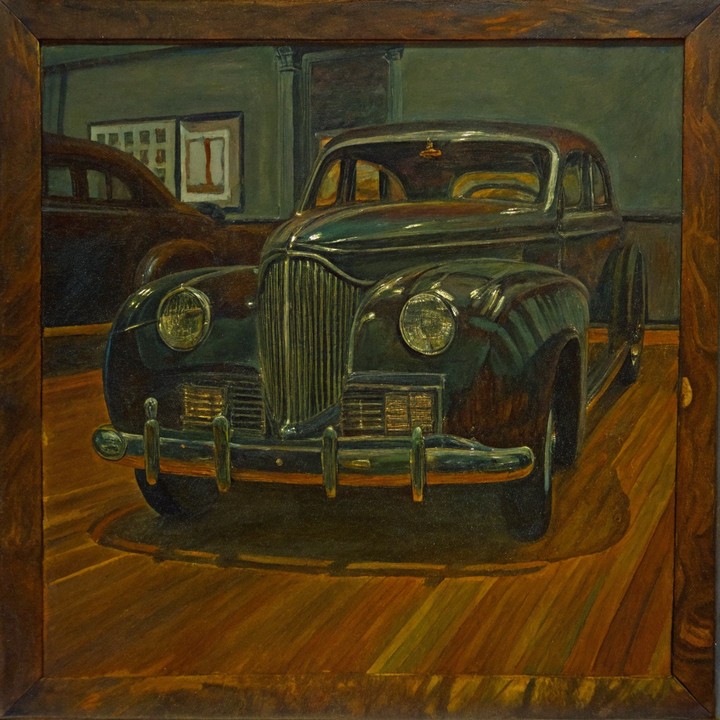 输入图像
输入已核验 · 同一 benchmark case · gap 0.1526
image_static_stylized_public_spaces_0029
套件: image_static场景: stylized / indoor / public_spaces
基准 prompt target
Camera orbit left. A vintage car display with wooden floor, framed artworks, and cars.
prompt source: prompt_target
两条视频的首帧都已通过与展示输入的几何匹配核验;高低标签只比较当前 metric。
较高指标分分数 0.3508
较低指标分分数 0.1982
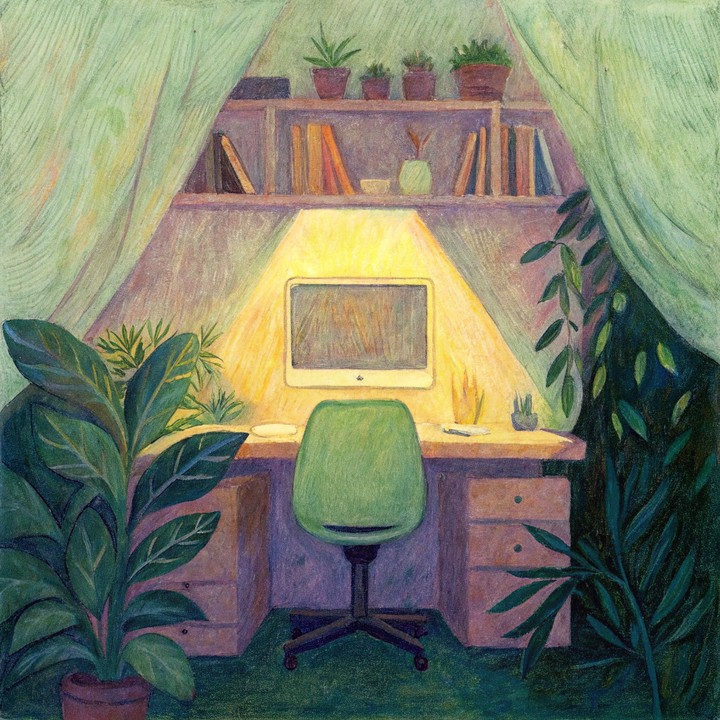 输入图像
输入已核验 · 同一 benchmark case · gap 0.1645
image_static_stylized_workspaces_0016
套件: image_static场景: stylized / indoor / workspaces
基准 prompt target
Camera pan right. A cozy workspace with desk, plants, and window.
prompt source: prompt_target
两条视频的首帧都已通过与展示输入的几何匹配核验;高低标签只比较当前 metric。
较高指标分分数 0.3426
较低指标分分数 0.1781
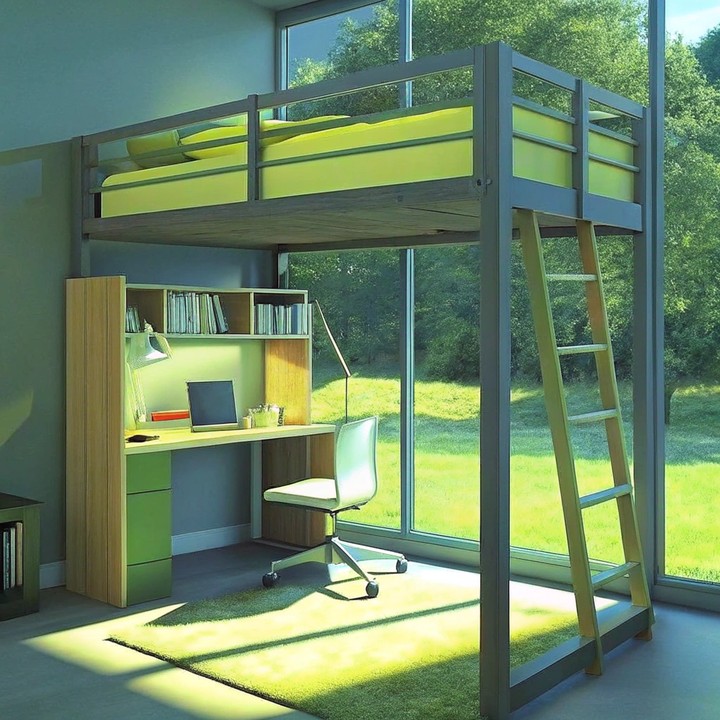 输入图像
输入已核验 · 同一 benchmark case · gap 0.1533
image_static_stylized_workspaces_0044
套件: image_static场景: stylized / indoor / workspaces
基准 prompt target
Camera pan right. A modern loft bed with bookshelf, indoor plant, and wall.
prompt source: prompt_target
两条视频的首帧都已通过与展示输入的几何匹配核验;高低标签只比较当前 metric。
较高指标分分数 0.3331
较低指标分分数 0.1798

