Skip to content

Perceptual Quality

perceptual_quality measures the no-reference visual quality of the prediction itself, without pairing prediction frames against a ground-truth reference rollout. It evaluates sharpness, cleanliness, and aesthetic plausibility at prediction anchor frames. It does not measure semantic correctness, prompt alignment, or geometric/physical compliance.

WorldAtlas fuses two complementary no-reference IQA signals into one perceptual score: CLIP-IQA+ captures overall visual naturalness and perceptual coherence, while the LAION aesthetic predictor captures aesthetic appeal. Both are scored independently on prediction anchors and then aggregated.

CLIP-IQA+ assesses holistic perceptual quality from CLIP visual–language representations. For anchor frame IiI_i, the model outputs a native score qinativeq_i^{\mathrm{native}}, normalized as:

siiqa=clip ⁣(qinative1, 0, 1)(1)s_i^{\mathrm{iqa}} = \mathrm{clip}\!\left(\frac{q_i^{\mathrm{native}}}{1},\, 0,\, 1\right) \tag{1}

The aesthetic score uses CLIP ViT-L/14 features with a LAION-Aesthetics linear regressor (pyiqa laion_aes). For anchor frame IiI_i:

siaes=clip ⁣(g(norm(CLIP(Ii)))10, 0, 1)(2)s_i^{\mathrm{aes}} = \mathrm{clip}\!\left(\frac{g(\mathrm{norm}(\mathrm{CLIP}(I_i)))}{10},\, 0,\, 1\right) \tag{2}

Per-frame perceptual quality is the arithmetic mean of both components:

si=siiqa+siaes2(3)s_i = \frac{s_i^{\mathrm{iqa}} + s_i^{\mathrm{aes}}}{2} \tag{3}

Given NN protocol-selected prediction anchor frames, the raw metric is:

Spq=1N∑i=1Nsi(4)S_{\mathrm{pq}} = \frac{1}{N}\sum_{i=1}^{N} s_i \tag{4}

Audit manifest: docs/assets/metric_examples/curated_same_case_manifest.json.

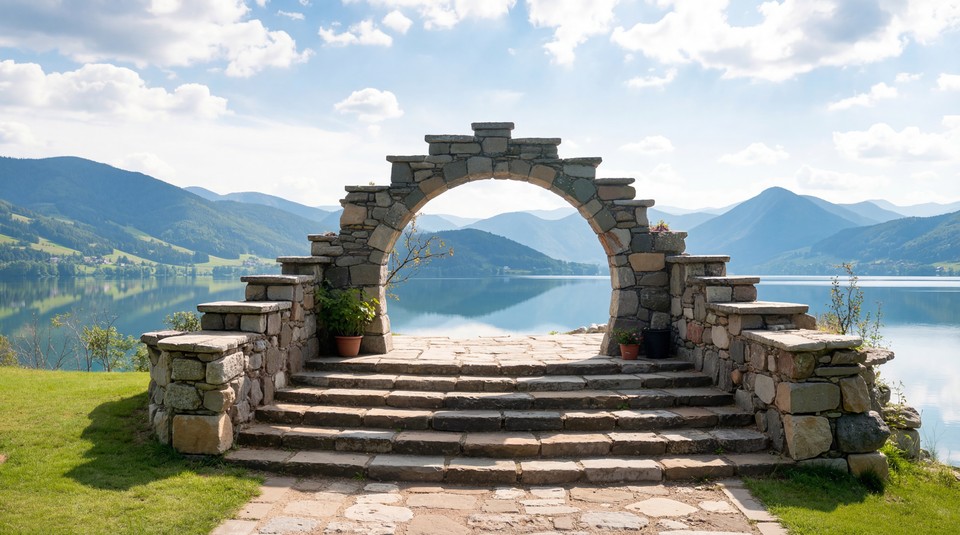
Input image: image_static_photorealistic_aquatic_landscape_0079
Input image
Input verified · same benchmark case · gap 0.3998

image_static_photorealistic_aquatic_landscape_0079

Suite: image_staticScene: photorealistic / outdoor / aquatic_landscape
Benchmark prompt target

Camera move right. A stone archway with pathway, grassy area, and mountains.

prompt source: prompt_target

Both first frames passed geometric matching against the displayed input; labels compare this metric only.

Model result videos will be available with the ModelScope release. / 模型推理视频将在 ModelScope 方案上线后提供。

Higher metric scoreScore 0.7155

Model result videos will be available with the ModelScope release. / 模型推理视频将在 ModelScope 方案上线后提供。

Lower metric scoreScore 0.3157
Input image: image_static_stylized_aquatic_landscape_0110
Input image
Input verified · same benchmark case · gap 0.3910

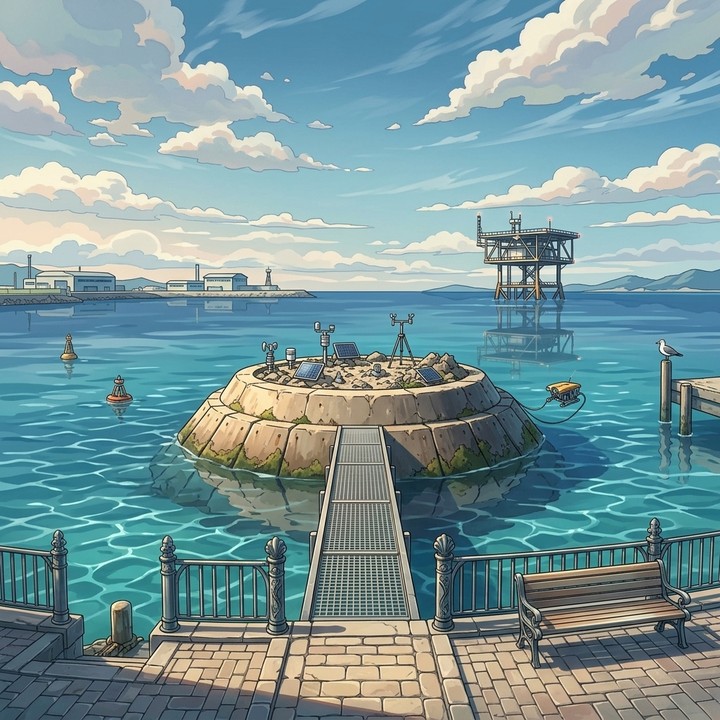
image_static_stylized_aquatic_landscape_0110

Suite: image_staticScene: stylized / outdoor / aquatic_landscape
Benchmark prompt target

Camera orbit right. An aquatic landscape with oil rig, industrial buildings, and rocky platform.

prompt source: prompt_target

Both first frames passed geometric matching against the displayed input; labels compare this metric only.

Model result videos will be available with the ModelScope release. / 模型推理视频将在 ModelScope 方案上线后提供。

Higher metric scoreScore 0.6485

Model result videos will be available with the ModelScope release. / 模型推理视频将在 ModelScope 方案上线后提供。

Lower metric scoreScore 0.2576

BibTeX — CLIP-IQA+
@inproceedings{wang2022exploring,
author = {Wang, Jianyi and Chan, Kelvin CK and Loy, Chen Change},
title = {Exploring CLIP for Assessing the Look and Feel of Images},
booktitle = {AAAI},
year = {2023}
}