2026-09-10: the active implementation is met3r_paper_consecutive_symmetric_v1. The former reference/anchor and reference_all_anchors_v2 scores are not paper-protocol MEt3R and must not be mixed with this version. CPU implementation tests are not pretrained GPU numerical certification.
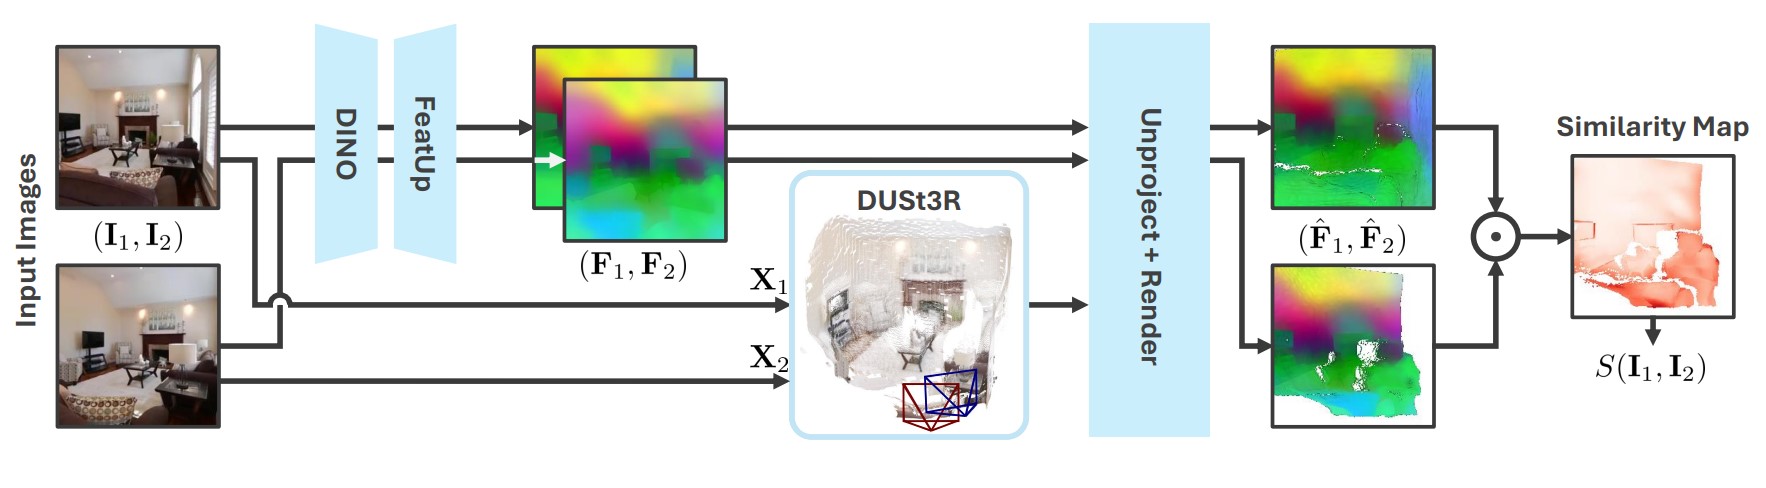
met3r_consistency follows the pairwise definition in MEt3R Asim et al., CVPR 2025: DUSt3R reconstruction, DINO16 features, FeatUp, overlap-weighted cosine dissimilarity. The author’s unchanged implementation is pinned to commit ee0e1752898559e1a3e85e2e151d3edeb9b55f73.
For each consecutive generated pair (I_t, I_{t+1}), the wrapper calls the official scorer in both directions and averages the two dissimilarities (paper Eq. 1). It then averages all consecutive-pair scores. The input image and any reference video are not paired with prediction frames. The global random-anchor sampler is not used.
MEt3R measures multi-view consistency in generated images through geometric and representation consistency across views.
Paper raw MEt3R lies in [0, 2], lower is better. The leaderboard computes clip(1 - raw/2, 0, 1) per video, then averages and multiplies by 100. It never inverts an averaged error_ref score. Report normalized fields may retain the compatibility transform; the final display value is score_details.published_score. Historical published summaries without matching per-video reports remain explicitly identified in score tooltips; they are not recomputed raw/scored means.
Zero-overlap outputs retain the official code’s finite value, with overlap diagnostics. There is no worst-score substitution, overlap-based sample deletion, or NaN repair. A finite zero for an empty overlap is an upstream edge case, not evidence that the views are consistent. Decode failures, invalid masks and non-finite scores fail the measurement.
Video input adaptation is explicit: use the entire supplied video at native stride 1, no temporal resampling or inserted conditioning image; resize RGB bilinearly with antialiasing to approximately 256² pixels, rounding ideal height to the nearest 32 pixels and width to the nearest 16 pixels (ties upward). The official FeatUp DINO patch embedder crops a row and column when its patch-grid height is odd, without adjusting positional encodings. An even patch-grid height avoids this incompatible path without changing official code or weights; previously compatible resize dimensions remain unchanged. The runtime records this convention as area_256_squared_height32_width16_bilinear_antialias. Rasterization follows the resulting dimensions. The paper specifies approximate area/aspect preservation but does not publish this exact rounding rule; it is a recorded input-adapter convention, not bit-exact reproduction of the authors’ video preprocessing. Dataset-specific 48/80-view limits in the paper are not silently imposed on WorldAtlas clips.
The paper’s DUSt3R route is selected explicitly; the newer official package’s default MASt3R route and non-FeatUp variants are rejected under this metric. FeatUp or DUSt3R dependencies missing on a worker cause a clear failure, never a bilinear substitute. New dependency locks and pretrained GPU direct-call parity are still required before release.
The historical examples below are retained for traceability only. They use superseded configurations/protocols and are not new-protocol results.
These representative comparisons were selected from the official 2026-07-17 image_static MEt3R snapshot and manually reviewed as frame strips. Each exhibit fixes one benchmark case—input image and eval-plan prompt target—and compares two prediction videos. The normalized MEt3R score is higher-is-better; raw MEt3R distance is lower-is-better.
Adapter-specific conditioning may differ, so these are metric diagnostics rather than controlled model rankings. Exact paths, hashes, overlap values, and report provenance are in the machine-readable MEt3R manifest.
Input image
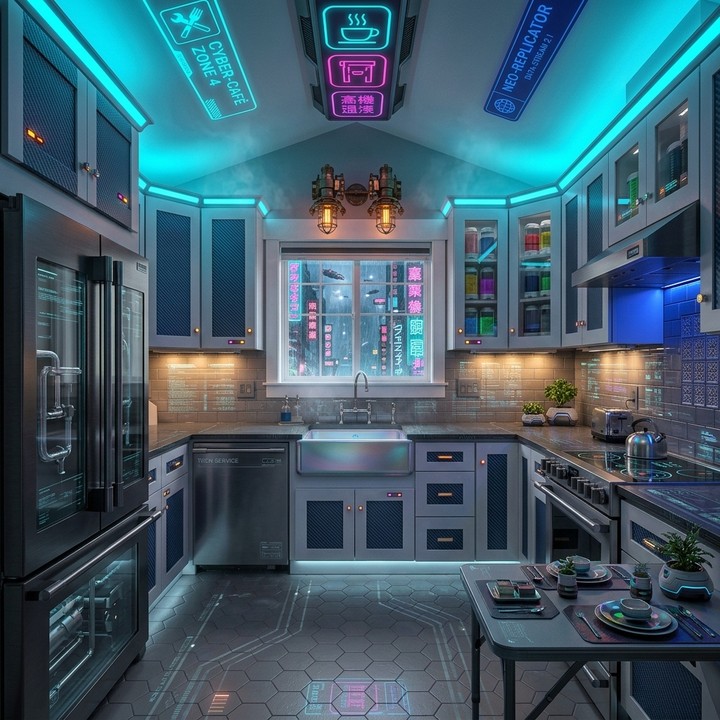
Case 1 · visible structural drift lowers multi-view consistency
image_static_stylized_dining_spaces_0115
image_staticstylized / indoor / dining_spaces
Benchmark prompt target
Camera pan right. A futuristic dining area with dining table, chairs, and digital displays. Camera pull out. A futuristic living room with sofa, digital screens, and neon accents. Camera move right. A futuristic balcony with neon signs, railing, and skyscrapers.
Output A follows the requested scene progression with stable, well-defined structure at the evaluated anchor. Output B develops translucent duplicate contours and warped room geometry; valid overlap drops and raw MEt3R distance rises.
Model result videos will be available with the ModelScope release. / 模型推理视频将在 ModelScope 方案上线后提供。
Output AMEt3R: 0.9823 normalized · 0.0354 raw · 0.9388 overlap
Model result videos will be available with the ModelScope release. / 模型推理视频将在 ModelScope 方案上线后提供。
Output BMEt3R: 0.5737 normalized · 0.8527 raw · 0.4778 overlap
Input image
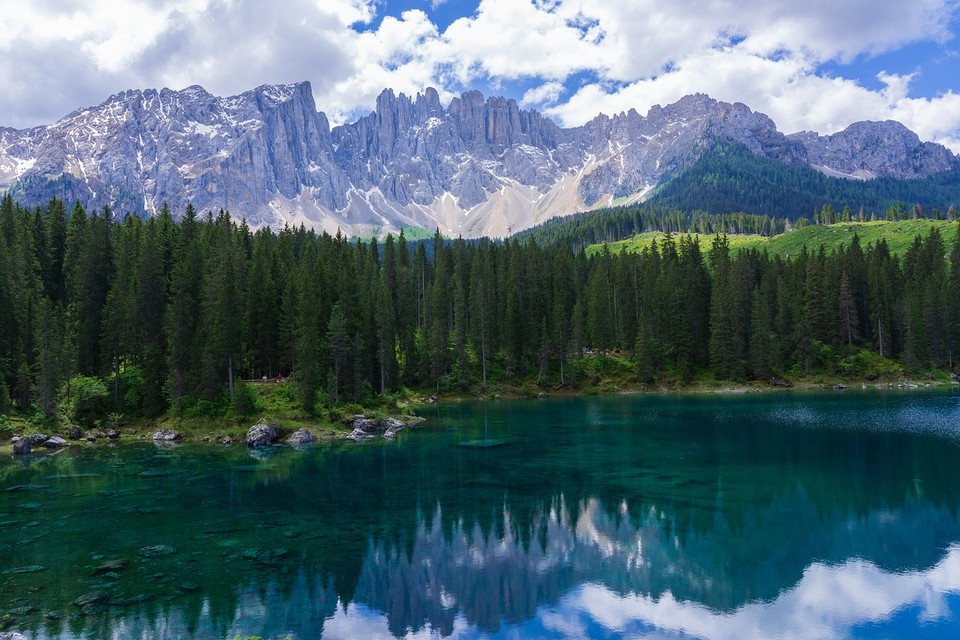
Case 2 · low anchor overlap after an abrupt view change
Camera pull out. A forest edge with rocky shore and trees. Camera pan right. A forest edge with open meadow, grassy field, and distant hills. Camera move right. A hiking trail with path through trees and small clearing.
Output A changes viewpoint gradually while retaining mountain, treeline, and shore structure. Output B jumps more abruptly toward the trail; at the evaluated anchor, valid projected overlap falls to 0.0529 and raw MEt3R distance increases.
Model result videos will be available with the ModelScope release. / 模型推理视频将在 ModelScope 方案上线后提供。
Output AMEt3R: 0.9559 normalized · 0.0883 raw · 0.8652 overlap
Model result videos will be available with the ModelScope release. / 模型推理视频将在 ModelScope 方案上线后提供。
Output BMEt3R: 0.7167 normalized · 0.5666 raw · 0.0529 overlap
Input image
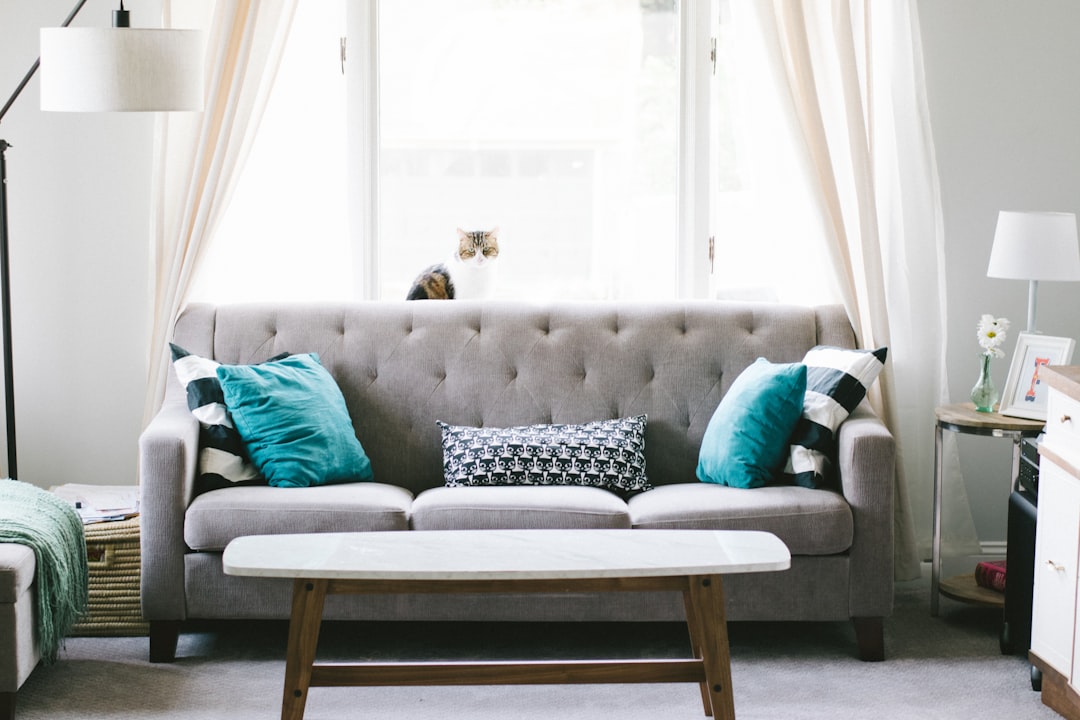
Case 3 · similar anchor consistency under different motion amounts
Camera push in. A living room with sofa, bookshelf, and books.
Output A moves little, while Output B makes a larger smooth camera move and reveals the bookshelf. At the evaluated MEt3R anchor, both retain high feature and projected-view consistency and therefore receive almost identical scores.
Model result videos will be available with the ModelScope release. / 模型推理视频将在 ModelScope 方案上线后提供。
Output AMEt3R: 0.9957 normalized · 0.0087 raw · 0.5406 overlap
Model result videos will be available with the ModelScope release. / 模型推理视频将在 ModelScope 方案上线后提供。
Output BMEt3R: 0.9972 normalized · 0.0055 raw · 0.5455 overlap