Skip to content

Camera Error

The current default, native_intended, uses MegaSAM poses to measure agreement with requested motion directions. The leaderboard averages per-video details.native_intent_accuracy and multiplies by 100. This is a direction-confidence score, not a metric-scale ground-truth trajectory error. The pose-alignment formulas below describe the separate direct pose-GT path: normalize rotation/translation using [0,15] / [0,0.5], take their geometric mean per video, then average videos. Report error_ref values remain compatibility inputs and are never inverted after averaging. Historical published summaries without matching per-video evidence are identified in the score tooltip and are not described as recomputed measurements.

Camera Error quantifies trajectory fidelity between a camera path recovered from a generated video and annotated ground-truth extrinsics. It measures viewpoint control compliance, not object motion or instruction following.

For the direct pose-GT policy, let {Ttgt}t=1N\{\mathbf{T}^{\mathrm{gt}}_t\}_{t=1}^{N} and {Ttpred}t=1N\{\mathbf{T}^{\mathrm{pred}}_t\}_{t=1}^{N} denote 4×44 \times 4 camera-to-world matrices from annotations and visual odometry (MegaSAM or DROID-SLAM). If the pose counts differ, the GT trajectory is uniformly resampled to the recovered pose count using linear translation interpolation and quaternion SLERP. WorldAtlas then estimates the full positive-scale similarity transform

s⋆,Q⋆,u⋆=arg⁡min⁡s>0, Q∈SO(3), u∑t=1N∥ttgt−(sQttpred+u)∥22(1)s^\star,\mathbf{Q}^\star,\mathbf{u}^\star = \arg\min_{s>0,\,\mathbf{Q}\in SO(3),\,\mathbf{u}} \sum_{t=1}^{N} \left\|\mathbf{t}^{\mathrm{gt}}_t- \left(s\mathbf{Q}\mathbf{t}^{\mathrm{pred}}_t+\mathbf{u}\right)\right\|_2^2 \tag{1}

with Umeyama alignment. Stationary or collinear paths use corresponding camera orientations to resolve the rotational gauge before solving scale and translation. The aligned prediction is R~t=Q⋆Rtpred\tilde{\mathbf{R}}_t=\mathbf{Q}^\star\mathbf{R}^{\mathrm{pred}}_t and t~t=s⋆Q⋆ttpred+u⋆\tilde{\mathbf{t}}_t=s^\star\mathbf{Q}^\star\mathbf{t}^{\mathrm{pred}}_t+\mathbf{u}^\star. Mean translation error is

Et=1N∑t=1N∥t~t−ttgt∥2(2)E_t = \frac{1}{N}\sum_{t=1}^{N} \left\|\tilde{\mathbf{t}}_t - \mathbf{t}^{\mathrm{gt}}_t\right\|_2 \tag{2}

Mean rotation error (degrees) uses relative rotation Rtrel=R~t(Rtgt)⊤\mathbf{R}^{\mathrm{rel}}_t = \tilde{\mathbf{R}}_t (\mathbf{R}^{\mathrm{gt}}_t)^\top:

Er=1N∑t=1Narccos⁡ ⁣(clip ⁣(tr(Rtrel)−12,−1,1))⋅180π(3)E_r = \frac{1}{N}\sum_{t=1}^{N} \arccos\!\left(\mathrm{clip}\!\left(\frac{\mathrm{tr}(\mathbf{R}^{\mathrm{rel}}_t) - 1}{2}, -1, 1\right)\right) \cdot \frac{180}{\pi} \tag{3}

WorldAtlas normalizes each direct-GT component to [0,1][0,1] with empirical ranges [0,15°][0, 15°] for rotation and [0,0.5][0, 0.5] for translation (lower is better), then combines them by the geometric mean. The default native_intended MegaSAM policy instead evaluates recovered motion against the requested camera/action directions and returns its native direction-confidence score; it does not use the direct-GT reducer above. The metric is official when the selected policy has sufficient camera supervision. It is not evaluated or published on image_dynamic.

Those direct-GT empirical ranges predate sim3_v1 and must be revalidated before publishing corrected direct-GT normalized scores. This does not affect the current default native_intended score surface.


Audit manifest: docs/assets/metric_examples/curated_same_case_manifest.json.

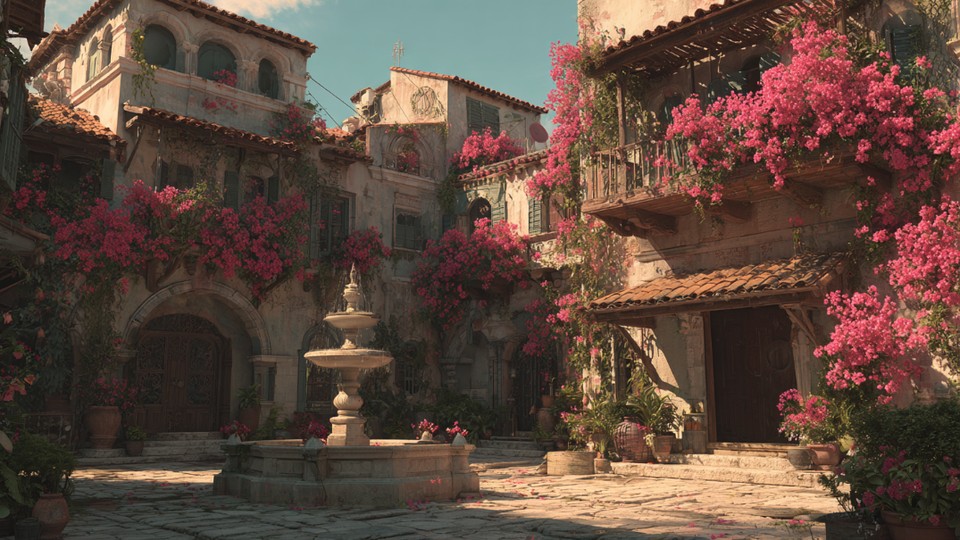
Input image: image_static_photorealistic_city_0038
Input image
Input verified · same benchmark case · gap 0.7722

image_static_photorealistic_city_0038

Suite: image_staticScene: photorealistic / outdoor / city
Benchmark prompt target

Camera orbit left. A mediterranean courtyard with fountain, stone benches, and bougainvillea.

prompt source: prompt_target

Both first frames passed geometric matching against the displayed input; labels compare this metric only.

Model result videos will be available with the ModelScope release. / 模型推理视频将在 ModelScope 方案上线后提供。

Higher metric scoreScore 0.9801Direction confidence 0.980 · ATE translation 0.103 · rotation 5.0°

Model result videos will be available with the ModelScope release. / 模型推理视频将在 ModelScope 方案上线后提供。

Lower metric scoreScore 0.2079Direction confidence 0.208 · ATE translation 1.035 · rotation 24.1°
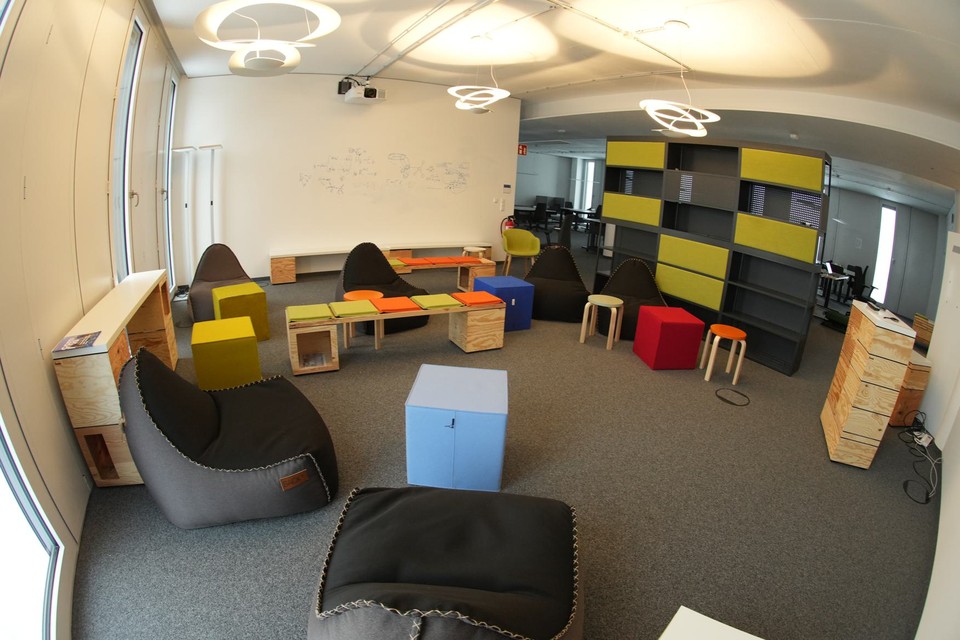
Input image: image_static_photorealistic_workspaces_0023
Input image
Input verified · same benchmark case · gap 0.9807

image_static_photorealistic_workspaces_0023

Suite: image_staticScene: photorealistic / indoor / workspaces
Benchmark prompt target

Camera move left. A modern workspace with desks, computers, and office chairs.

prompt source: prompt_target

Both first frames passed geometric matching against the displayed input; labels compare this metric only.

Model result videos will be available with the ModelScope release. / 模型推理视频将在 ModelScope 方案上线后提供。

Higher metric scoreScore 0.9990Direction confidence 0.999 · ATE translation 0.054 · rotation 7.0°

Model result videos will be available with the ModelScope release. / 模型推理视频将在 ModelScope 方案上线后提供。

Lower metric scoreScore 0.0183Direction confidence 0.018 · ATE translation 0.760 · rotation 15.7°
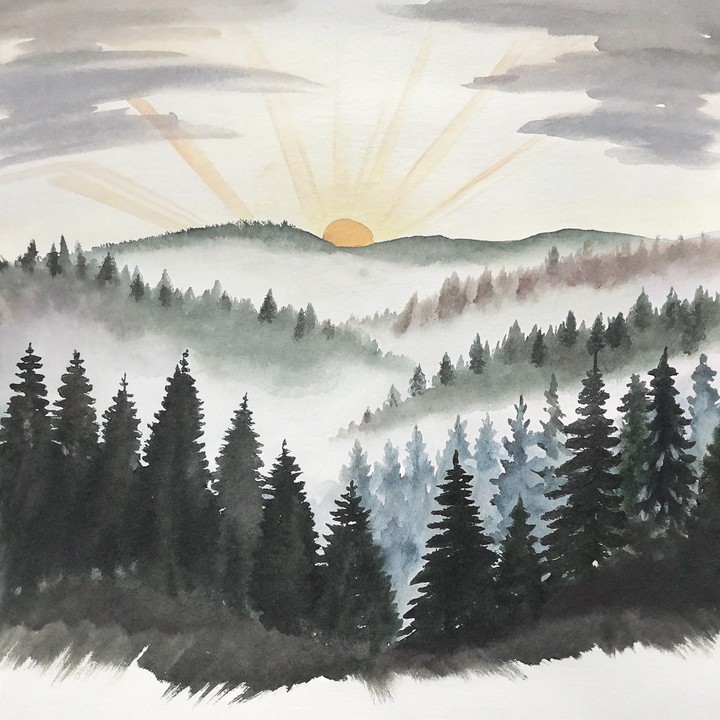
Input image: image_static_stylized_terrestrial_landscape_0102
Input image
Input verified · same benchmark case · gap 0.8186

image_static_stylized_terrestrial_landscape_0102

Suite: image_staticScene: stylized / outdoor / terrestrial_landscape
Benchmark prompt target

Camera move left. A forest edge with clearing, sunlight, and trees.

prompt source: prompt_target

Both first frames passed geometric matching against the displayed input; labels compare this metric only.

Model result videos will be available with the ModelScope release. / 模型推理视频将在 ModelScope 方案上线后提供。

Higher metric scoreScore 0.9810Direction confidence 0.981 · ATE translation 0.044 · rotation 0.1°

Model result videos will be available with the ModelScope release. / 模型推理视频将在 ModelScope 方案上线后提供。

Lower metric scoreScore 0.1623Direction confidence 0.162 · ATE translation 0.106 · rotation 6.3°